AI Tracker
Multimodal news,
for builders.
The latest multimodal news from every AI provider: launches, price changes and retirements, summarized with what they mean for you.
Liquid AI introduces LFM3, six small models across text, vision, audio and omni
Liquid AI announced LFM3, a new generation of its Liquid Foundation Models built on what it calls a new tri-hybrid architecture, with new multimodal encoders. It says the architecture is optimized for 14 processor classes across GPUs, CPUs and NPUs, and that the models can be fine-tuned on one GPU.Google DeepMind introduces Genie 4, a real-time interactive world model
Google DeepMind announced Genie 4 on October 27, 2026, calling it its most realistic and interactive world model yet. In its post, DeepMind says users can explore dynamic environments in real time and see how the scene responds, sounds, and how the people in it move, react and speak. It published a blog post, "Genie 4: a new generation of world simulation".Microsoft's MAI-Image-2.7-Preview ranks #2 on Artificial Analysis image editing
Artificial Analysis says Microsoft AI's MAI-Image-2.7-Preview, the newest image editing model and successor to MAI-Image-2.6 (released in August), takes second place on its AA-Image-Editing v2.1 leaderboard, close behind OpenAI's GPT Image 2.5 Sunburst (max). The results are Artificial Analysis's own.SenseTime reportedly open-sources SenseNova 6.8 Code2Video, a 27B code-to-video model
A Chinese AI blogger reports that SenseTime open-sourced SenseNova 6.8 Code2Video on October 27, with weights on Hugging Face under sensenova/SenseNova-6.8-Code2Video. The report is second-hand; SenseTime's own announcement is not cited.Maya-2, a voice model for Indian languages, is released with open weights
Maya-2, a voice (speech synthesis) model aimed at India, was published with open weights on October 27 under the Hugging Face name maya-research/maya2-native. The announcement on X says it covers more than 1.5 billion people across all 28 states and 8 union territories.
Baidu open-sources Unlimited OCR 2, a document parser with near-constant decoding cost
Baidu announced Unlimited OCR 2 on X on October 26, with code on GitHub and weights on Hugging Face. The model is built to parse documents of virtually any length within a finite context window.Artificial Analysis launches Code2Video-AA, a benchmark of marketing videos made in code
Artificial Analysis introduced Code2Video-AA, its own implementation of HeyGen's Code2Video Bench, built in partnership with HeyGen. Models get 114 product and brand marketing briefs and must answer each with a HyperFrames HTML composition in a single response, without tools; the composition is rendered to video with no network access. A judge model (Gemini 4 Argon, high) compares pairs of videos on engagement, prompt intent, composition, temporal consistency and craft, and the five axis Elo ratings are averaged into the headline score. More than 35,000 verdicts rank 27 models. The results are Artificial Analysis's own.A fine-tuned 2015 CNN beats GPT-6 Astra and Claude Fable 5.1 at naming skin lesions, a dermatologist reports
Dr Magnus Lynch, a consultant dermatologist at Guy's Hospital and King's College London, published a test of GPT-6 Astra and Claude Fable 5.1 on 200 biopsy-proven lesions drawn at random from the public MILK10k dataset. Each model got a clinical photograph and a dermoscopic image, the same prompt and default settings, and chose among six diagnoses. The comparison model was Inception v3 (published 2015), fine-tuned on 68,011 images from the ISIC Archive on one H100 GPU, with the test lesions removed from its training data.Moonshot launches Kimi K3.1 Pro, with open weights due by November 4
Moonshot announced Kimi K3.1 Pro, which it calls its most capable 3T-class open-weight model: a multimodal mixture-of-experts model with 2.8T total and 104B active parameters and a 1M-token context. Moonshot says K3.1 Pro and K3.1 Pro Highspeed (2–3× faster) are live on Kimi.ai, Kimi Work, Kimi Code and the Kimi API (model ids kimi-k3.1-pro and kimi-k3.1-pro-highspeed). Open weights are promised by November 4, 2026.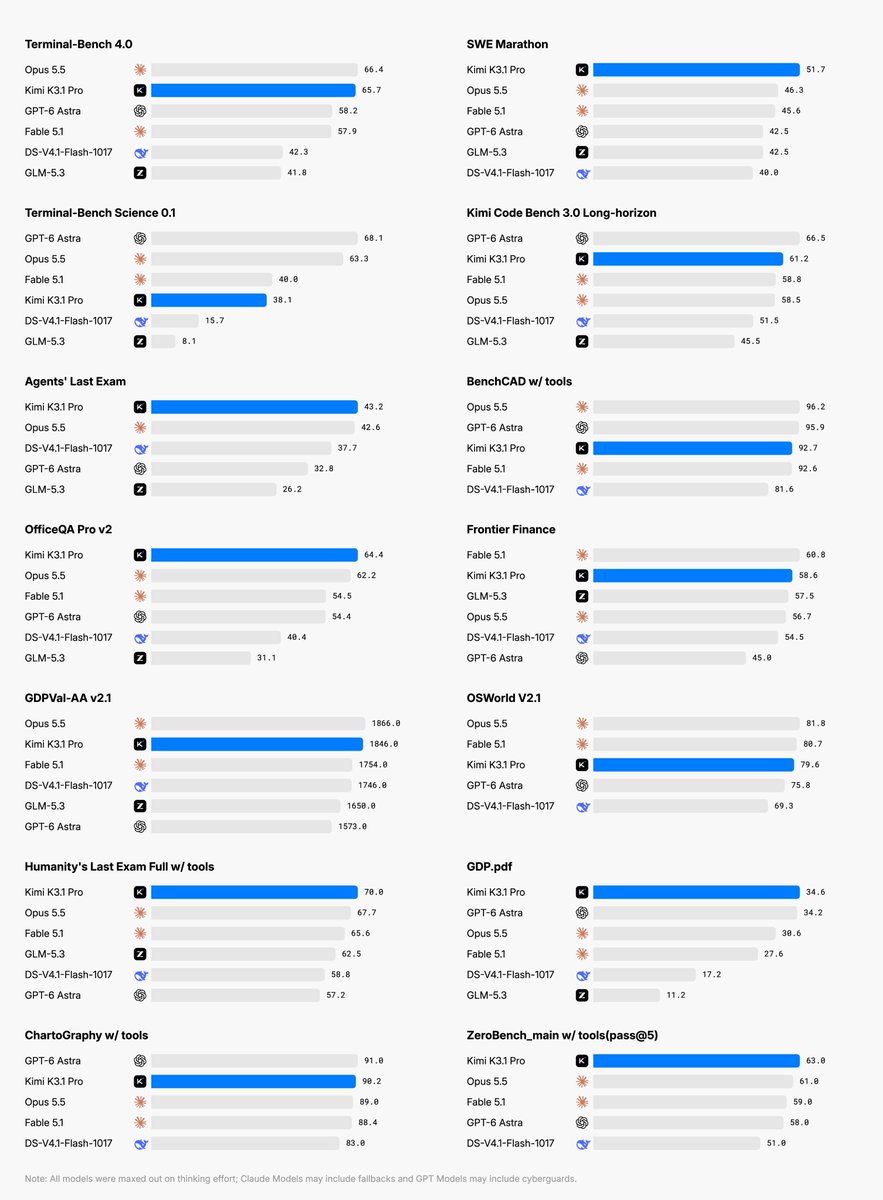
Block previews Dessa, a full-duplex speech-to-speech model
Block, the company behind Square and Cash App, introduced a research preview of Dessa, which it calls "the most authentic full-duplex speech model ever built". Jack Dorsey's announcement says that talking with it feels like talking with a person, with emotion, nuance, pauses and natural cadence.Google releases Gemini 4 Argon, its latest frontier model
Google released Gemini 4 Argon on October 13, 2026, and says it is available globally. Google's blog post was shared on Hacker News on October 20. The Gemini API changelog lists gemini-4-argon as generally available from October 13, describing it as Google's most capable model, built for complex coding, agentic, math and science tasks.Grok Bot 0.75.2 adds cards in desktop chats and video generation
Grok Bot 0.75.2 is out, according to a post on X from a member of the Grok Bot team that links to the release's changelog on x.ai. The post lists three changes:Ideogram introduces its first vector model
Ideogram announced its first vector model on X. According to Ideogram, it generates clean, editable SVGs with smooth gradients and sharp typography from a text prompt, or turns any image into a detailed, scalable vector.
Mistral releases Voxtral 3, speech models and a voice agent SDK
Mistral announced Voxtral 3 on October 20, 2026 (shared on Hacker News, where it had 735 points and 182 comments by October 20). Details and benchmarks below are Mistral's own claims from its announcement page.
ElevenLabs opens a limited alpha of Eleven Realtime Translation
ElevenLabs announced on X on October 21, 2026 a limited alpha of Eleven Realtime Translation, which builds live voice translation into calls. It followed the launch earlier that week of Eleven Realtime, its product for voice agents that talk to people.