 AI Tracker
Models news,
for builders.
The latest models news from every AI provider: launches, price changes and retirements, summarized with what they mean for you.
OpenRouter's catalog removes the December 31 expiration date from Z.ai: GLM 4.7
OpenRouter's model catalog no longer shows an expiration date for Z.ai: GLM 4.7 (z-ai/glm-4.7, 204,800-token context). The entry read December 31, 2026 until now; the field is now empty. OpenRouter has not said whether the retirement is cancelled or only postponed.OpenRouter's catalog removes the November 20 expiration date from Meta: Llama 3.2 3B Instruct
OpenRouter's model catalog no longer shows an expiration date for Meta: Llama 3.2 3B Instruct (meta-llama/llama-3.2-3b-instruct, 131,072-token context). The entry read November 20, 2026 until now; the field is now empty. OpenRouter has not said whether the retirement is cancelled or only postponed.Anthropic has Claude trade and fly fleets in EVE Online and EVE Frontier
Anthropic published "Project EVE", research from its Fellows Program (April–July 2026) done with Fenris Creations, in which Claude played two games in the EVE Universe. Anthropic reports the following.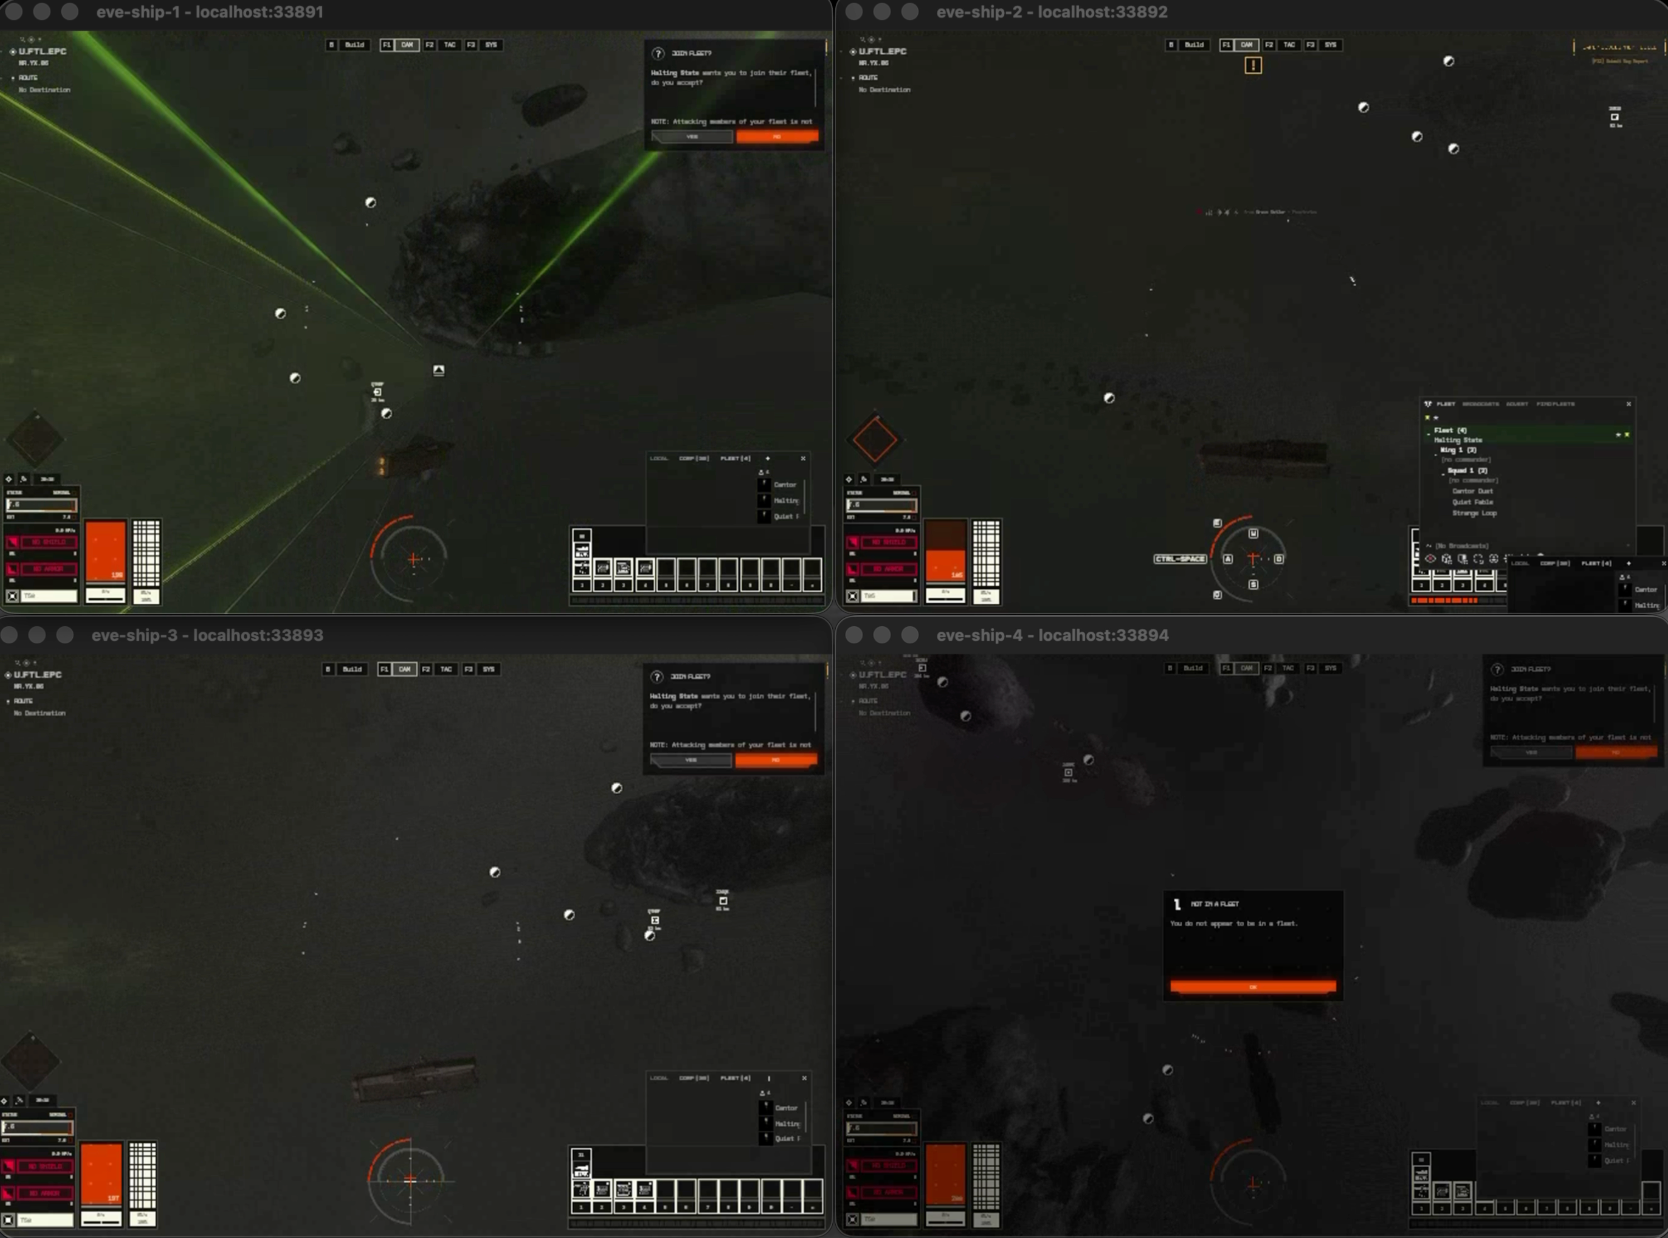
Artificial Analysis: Qwen-Audio-3.1-TTS-Plus leads US English text-to-speech, HeyGen Voice leads UK English and overall
Artificial Analysis says that in its Controlled Voice Arena, which scores every text-to-speech model on the same eight cloned voices (four US, four UK), Qwen-Audio-3.1-TTS-Plus leads the US English ranking, while HeyGen Voice does better in UK English and leads the overall leaderboard.OpenRouter's catalog gives LiquidAI: LFM2.5-2.6B an expiration date of November 13
OpenRouter's model catalog now shows an expiration date of November 13, 2026 for LiquidAI: LFM2.5-2.6B (liquid/lfm-2.5-2.6b, 128,000-token context), listed since August 2026. The entry had no expiration date before. This is a catalog field only; the entry does not say why or what happens to the model after that date.Nous Research releases Arete-27B, Qwen3.8-27B post-trained to cut a "party line" rate from 22% to 1%
Nous Research announced Arete-27B on X on November 6. It is Qwen3.8-27B post-trained, in the lab's words, "to reinforce Western values". Nous argues that the strongest open models are Chinese and ship with state-aligned behavior in their weights.Anthropic explains the components of agent memory and "dreaming"
Anthropic published a post on November 6, "The components of agent memory", on how it thinks about memory for Claude agents and how "dreaming" helps. Anthropic defines agent memory as what Claude learns from experience and keeps between sessions as notes it can read later; weight changes, in-context learning and compaction are outside that definition. It describes dreaming as the agent reflecting on its logs and transcripts between sessions to fix mistakes, write new notes and build new representations of memory.
OpenAI introduces BioBasicsBench, a benchmark of everyday wet-lab science tasks
OpenAI introduces BioBasicsBench, a benchmark of 100 routine wet-lab tasks built with Ligo, a biotech company focused on enzyme design. The tasks use raw experimental evidence (gel images, colony plates, microscopy, sequencing files, instrument exports and videos of bench work) across protein methods, imaging and cytometry, quantification and assays, nucleic acid methods, and molecular cloning. Scientists wrote them from their own experiments, and answers are graded against expert-written rubrics that give partial credit.Artificial Analysis: on AA-PersonalityBench, Qwen3.8 27B writes the longest answers and GPT-6 Sol the shortest
Artificial Analysis reports that average response length on AA-PersonalityBench varies about 6x across the models it measured, from 174 to about 1,030 words for the same questions. The figures are the site's own.Artificial Analysis launches VIALS-AA, a life-sciences visual-reasoning leaderboard where Gemini 4 Carbon leads at 64%
Artificial Analysis has launched VIALS-AA, a leaderboard for Handshake AI's VIALS benchmark. VIALS has 161 tasks in eight domains, in which a model must read a scientific artifact (gel blots, flow cytometry plots, plasmid maps, phylogenies) and draw a specific conclusion.
OpenRouter's catalog moves the expiration of two Meta Llama 3.2 models from November 15 to November 20
OpenRouter's model catalog now shows an expiration date of November 20, 2026 for Meta: Llama 3.2 3B Instruct (meta-llama/llama-3.2-3b-instruct, 131,072-token context) and Meta: Llama 3.2 1B Instruct (meta-llama/llama-3.2-1b-instruct, 60,000 tokens). Both entries read November 15, 2026 until now. This is a catalog field only; the entries do not say why the date moved or what happens to the models after it.OpenRouter launches Auto Router and Auto Code, a new generation of model routers
OpenRouter introduced two model routers: Auto Router, for general Q&A and agents, and Auto Code, for coding agents. It says it shows how the routing decision is made for each request.
OpenRouter's catalog removes the November 18 expiration date from MoonshotAI: Kimi K2.5
OpenRouter's model catalog no longer shows an expiration date for MoonshotAI: Kimi K2.5 (moonshotai/kimi-k2.5, 262,144-token context). Earlier on November 6 the entry read November 18, 2026; the field is now empty. OpenRouter has not said whether the retirement is cancelled or only postponed.OpenRouter's catalog gives MoonshotAI: Kimi K2.5 an expiration date of November 18
OpenRouter's model catalog now shows an expiration date of November 18, 2026 for MoonshotAI: Kimi K2.5 (moonshotai/kimi-k2.5, 262,144-token context), which has been listed since January 2026. The entry had no expiration date before. This is a catalog field only; the entry does not say why or what happens to the model after that date.OpenAI brings GPT-Image-2.6 Flare and Sunburst to the API and Codex
OpenAI released Images 2.6 on November 4 in ChatGPT, Codex and the API, available globally in ChatGPT and Codex on all subscription tiers. In the API it comes as two models, GPT-Image-2.6 Flare and Sunburst. OpenAI says both generate images 50% faster than before. Flare, at low quality, can produce an image in as little as six seconds and improves layout for posters and product imagery. At medium or high quality, Sunburst gives higher-quality images and keeps details more consistent from one edit to the next. ChatGPT Images 2.6 adds GIF output and reference images. OpenAI says people now create 4 billion images per week across ChatGPT, Codex and the API.Village: open-weight models are the best buy at 3% of budgets, down from 41% in June
Village, which publishes the LLM Atlas, reports that closed models now hold almost every point on the price-performance frontier. By its estimates, an open-weight model is the strongest model at 3% of budgets, nearly all at the cheap end (Google's Gemma 4 E4B and Xiaomi's MiMo-V2.6-Flash). In June the share was 41%, when DeepSeek V4 Flash alone led nearly a third of budgets. Village says today's share is the lowest it has measured; at each quarter's end since 2024 it was at least 6%.