 AI Tracker
Multimodal news,
for builders.
The latest multimodal news from every AI provider: launches, price changes and retirements, summarized with what they mean for you.
Hume launches the Audio Decision API, which answers questions about audio in one call
Hume says its Audio Decision API lets developers ask questions about audio, such as how many speakers there are, whether anyone is laughing or whether a caller is frustrated. Hume says this replaces work that used to take 10 or more models.Meituan releases LongCat-2.5, a 1.6T-parameter multimodal model for agent tasks
Meituan has released LongCat-2.5, according to an X post by the account leo114119 that links Meituan's LongCat blog. The post says Meituan describes it as a native multimodal model built for agent tasks, with 1.6 trillion parameters, and as strong on complex visual coding projects and professional office work such as creative design, 3D tasks and business analysis.
Google announces Gemini 4 Carbon, its next frontier model, to cyber defenders first
Google announced Gemini 4 Carbon on October 28, 2026, calling it its strongest model, with state-of-the-art cybersecurity and long-horizon capabilities. It follows Gemini 4 Argon by two weeks. Sundar Pichai's post and Google's blog say it is not yet generally available: starting this week a subset of cyber defenders get access, with more trusted partners added through the Fairwind Program. Google says it will bring Carbon to developers, businesses and consumers "as soon as possible", and that it is taking part in the U.S. government's voluntary process for pre-release model testing.
Hex, a local voice-input app for talking to coding agents, reaches a stable release
The OpenCode account said on X on October 31 that a stable release of Hex is available. It describes Hex as a way to talk to any agent by voice that is fast, runs locally and works on Mac, Windows and Linux. The post links to anoma.ly/hex.OpenCode 2.2.3 adds an image generation tool
The OpenCode account said on X on October 30 that OpenCode 2.2.3 has an image generation tool that supports image models from OpenAI, Gemini, Grok and others. It suggests using it for concept UI or reference art for video games.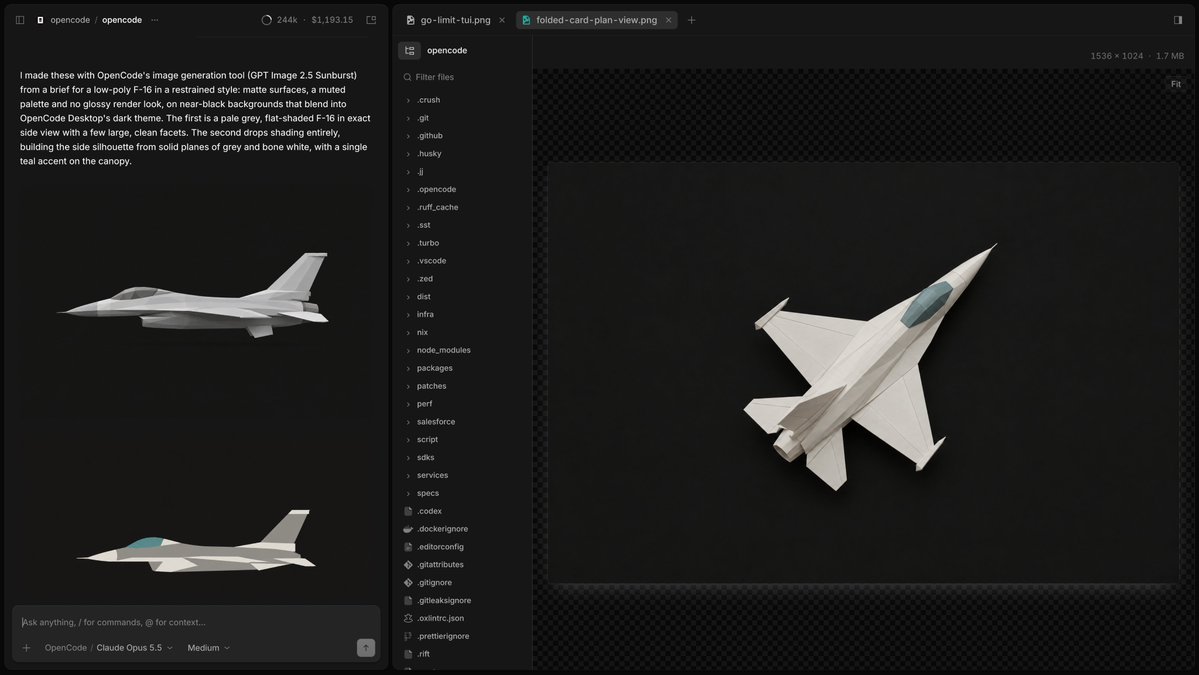
ElevenLabs releases SFX v3, a sound-effects model that follows multi-part prompts
ElevenLabs released SFX v3, its latest sound-effects model. It says the model makes richer, more precise sound effects from a single text prompt, follows several instructions in one prompt more reliably (its example: a crowd cheering, a ball dropping, then a crowd booing), and has improved music and vocals.PokeBot launches RoboAPI, an API that gives robot arms natural-language instructions
PokeBot introduced RoboAPI on October 29, powered by Poke-Aurora, which it calls its world-action model. It says compatible robots can take natural-language instructions through a simple API, with no task-specific training.Pika launches H3 Flex, a fast video model it calls the top open-weight text-to-video model on DesignArena
Pika introduced H3 Flex, which it says debuts as the #1 open-weight model on DesignArena's text-to-video board (Pika's claim). It describes the model as built for professional iteration: exportable audio stems, resolutions up to 4K and faster-than-realtime generation, with a 15-second clip and soundtrack in as little as 7 seconds.Phonic 1 debuts at #1 on Artificial Analysis's Speech to Speech Index
Artificial Analysis (a benchmark site, its own measurements) says Phonic 1 (High), the speech-to-speech model from Phonic, takes #1 of 22 on its Speech to Speech Index at 87.1, narrowly ahead of Grok Voice 3.0 (86.9). The model is available through the Phonic API at $0.07 per minute.Fish Audio releases Drama 3, which Artificial Analysis ranks #1 among open-weight speech models
Fish Audio released Drama 3, with weights on Hugging Face. Artificial Analysis (a benchmark site, its own measurements) says it is the #1 open-weights model on both of its speech arenas and #1 of all models on its Pronunciation Robustness benchmark.Artificial Analysis shows AA-Robotics v0.1, a benchmark of models controlling a robot arm
Artificial Analysis published AA-Robotics v0.1, which has models control a robot arm and shows the task from the model's point of view. In an example where the same robot writes "hello world", Artificial Analysis says Claude Opus 5.5 dabbed it out dot by dot, with 3,270 arm moves over 34 minutes, while GPT-6 Astra wrote in continuous strokes, with 514 moves in 13 minutes.ElevenLabs introduces Cue, a forced alignment model
ElevenLabs research introduced Cue, a forced alignment model: the step that turns a transcript into timestamps, used for subtitles, dubbing and clickable transcripts. It places every character on the audio timeline.Rime launches Prism, a speech-to-speech model for voice agents
Rime launched Prism, a speech-to-speech model for AI voice agents. The figures below are Rime's own claims, not independently measured.Artificial Analysis launches AA-Video-I2V v2.1, a benchmark for image-to-video models
Artificial Analysis launched AA-Video-I2V v2.1 and AA-Video-I2V-Silent v2.1, a benchmark for image-to-video models. Each prompt pairs a 1080p starting image with a prompt written for it and is tagged by use case, capability and visual style; models are judged at up to 1080p and ranked across 10 use cases and 10 capabilities. The overall ranking samples evenly across them. The results are Artificial Analysis's own.
OpenBMB releases MiniCPM-OCR, a 1B document parser, with a 2B model that scores OCR results
OpenBMB showed MiniCPM-OCR on X on October 28, running locally on an iPhone and an iPad. It is released with open weights and can run with llama.cpp, vLLM, SGLang or Ollama; fine-tuning code is open source, and OpenBMB also offers a demo and an API.AssemblyAI launches its first text-to-speech model, AssemblyAI-TTS-1
AssemblyAI launched AssemblyAI-TTS-1, its first text-to-speech model, built for voice agents. AssemblyAI says it streams in 90 ms at $15 per million characters and calls it the best TTS model you can run at scale on accuracy, naturalness and cost together. OpenRouter says the model is live there, with 4,000+ voices served from the US or EU.