 AI Tracker
Artificial Analysis releases Coding Agent Index v2.0; Claude Code with Opus 5.5 leads at 61.7
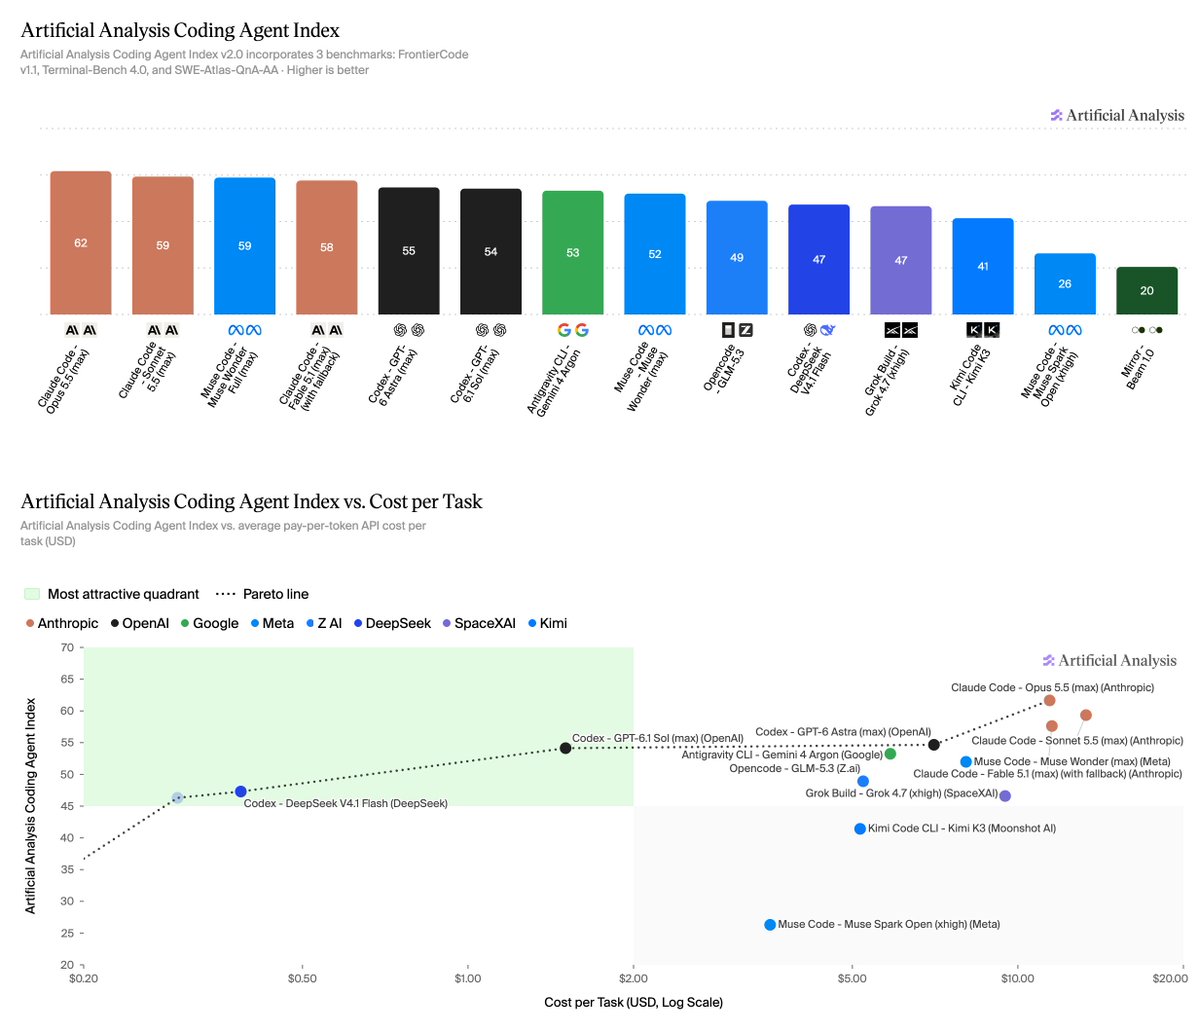
Artificial Analysis launched v2.0 of its Coding Agent Index, which scores models together with their agent harnesses on 290 tasks across software engineering, terminal use and repository Q&A, weighted equally. The scores are Artificial Analysis's own, not independently verified.
What changed from v1.5:
- FrontierCode v1.1 from Cognition replaces DeepSWE v1.1. It has 100 tasks on real open-source repositories with a private test set, graded on whether a maintainer would merge the change; an attempt flagged for accessing solution material scores zero.
- SWE-Atlas-QnA-AA revises the grading of Scale AI's 124 repository Q&A tasks: 127 of 1,306 rubric criteria were reworded and the judge is now GPT-6 Luna (xhigh) with five votes per criterion.
- Terminal-Bench 4.0 is unchanged.
- Scores are lower for almost every configuration measured on both versions: the mean falls from 54.8 to 47.4, mostly because of FrontierCode (45.1% average against 65.6% on DeepSWE).
Results:
- Index: Claude Code with Claude Opus 5.5 (max) scores 61.7, ahead of Claude Code with Claude Sonnet 5.5 (59.3), Muse Code with Muse Wonder Full (58.9) and Claude Code with Claude Fable 5.1 (57.6).
- FrontierCode: Opus 5.5 scores 56.0%, followed by Codex with DeepSeek V4.1 Flash (52.6%), Codex with GPT-6.1 Sol (49.4%) and Codex with GPT-6 Astra (49.3%). 15 of the 24 configurations score between 43% and 49%.
- SWE-Atlas-QnA-AA: Muse Code with Muse Wonder Full leads at 68.8%, then Claude Code with Fable 5.1 (66.4%) and Opus 5.5 (65.9%).
- Cost per task (pay-per-token API costs): Codex with DeepSeek V4.1 Flash scores 47.3 at $0.39, Codex with GPT-6.1 Sol 54.1 at $1.50, Codex with GPT-6 Astra 54.7 at $7.04, and Claude Code with Opus 5.5 61.7 at $11.42.
Sources
Discussions
Get news like this as a push.
AI Tracker alerts you when something changes for the tools you use.