 AI Tracker
Artificial Analysis: without tools, Claude Fable 5.2 drops from 67% to 44% on VIALS-AA, below Haiku 5.5 with tools
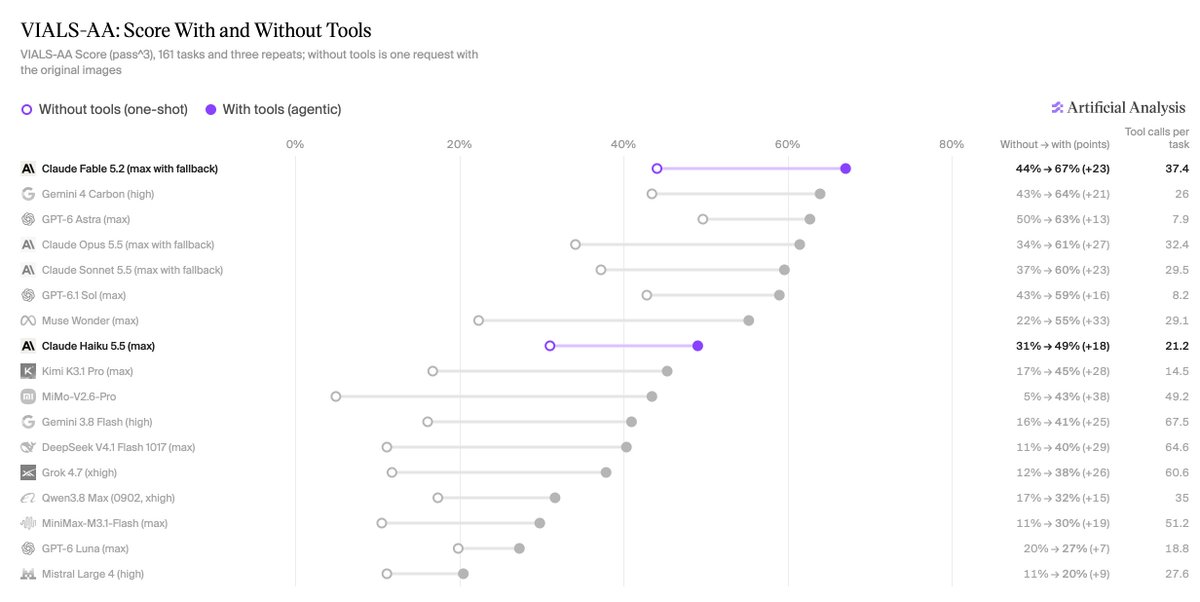
Artificial Analysis reran VIALS-AA, its life-sciences visual-reasoning benchmark, in a one-shot format: a single request with the question and images, and no tools. By default the benchmark has models work as agents that think, run code and view images in a sandbox. Across models, it says, tool use nearly doubles scores, from about 25% to about 47% on average.
- Fable 5.2 (max): 67% with tools at $4.20 per task; 44% without tools at $0.73 per task, which is below Claude Haiku 5.5 (max) with tools.
- Haiku 5.5 (max): 49% with tools at $0.07 per task. Artificial Analysis says the cheapest way to a given score is often a smaller model with tools: Claude Opus 5.5 without tools scores 34% at $0.33.
- Counting tasks: on the 23 cell-counting and quantification tasks, Fable falls from a 65% pass^3 rate with tools to 9% without; Opus 5.5 from 57% to 4%; Claude Sonnet 5.5 from 65% to 13%. GPT-6 Astra falls from 61% to 35% and GPT-6.1 Sol from 61% to 39%. On the 23 phylogenetics tasks Astra passes 78% with tools and 83% without.
- Who gains most: the ten models scoring below 31% without tools average about 42 tool calls per task, the seven above about 23. MiMo-V2.6-Pro goes from 5% to 43% with about 49 calls per task; Gemini 3.8 Flash (high) from 16% to 41% with about 68. Astra and Sol make about 8 calls per task and gain 13 and 16 points.
- Cost: tools raise cost per task for every model, from Astra's $0.21 to $0.27 up to Fable's 5.8× increase; the largest multiples are Qwen3.8 Max (0902, xhigh) at 28×, Gemini 3.8 Flash at 20× and MiMo-V2.6-Pro at 15×.
These are Artificial Analysis's own measurements.
Sources
Get news like this as a push.
AI Tracker alerts you when something changes for the tools you use.