 AI Tracker
vLLM says it now matches DeepSeek's DeepInfer engine on DeepSeek-V4.1-Flash
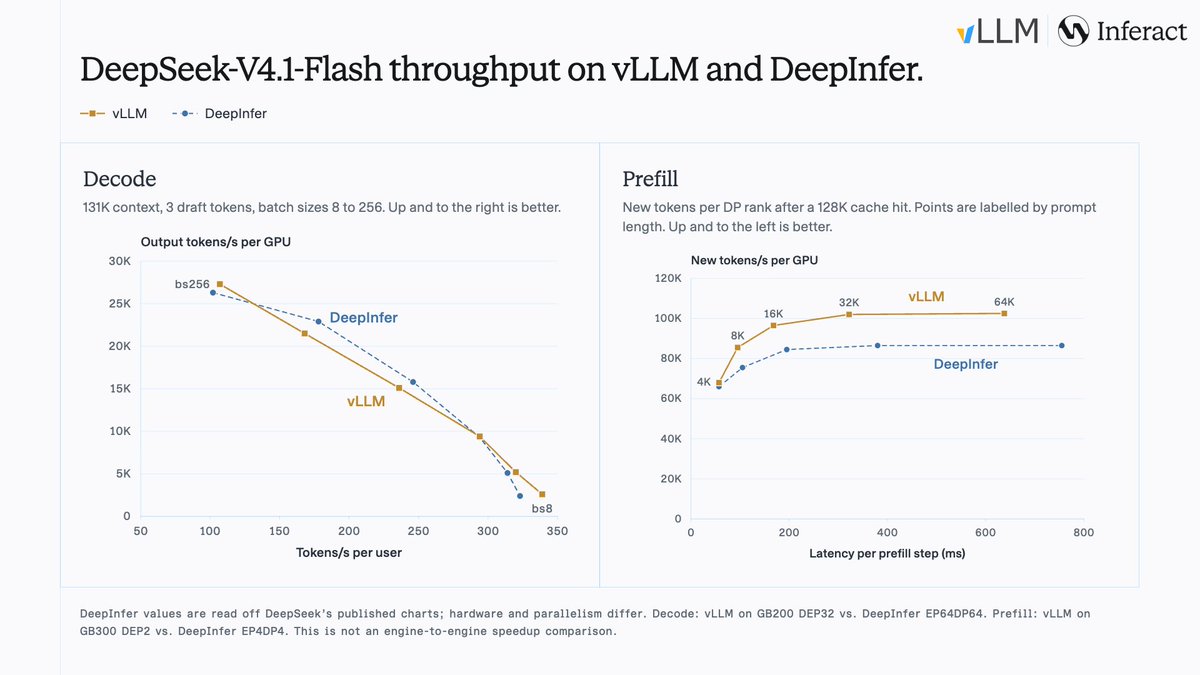
The vLLM project says its inference engine now matches DeepInfer, DeepSeek's own engine for DeepSeek-V4.1-Flash, on DeepSeek's decode configuration across batch sizes 8 to 256. It says it does so at DEP32 (data-parallel attention with expert parallelism over 32 GPUs), against DeepInfer's EP64DP64 setup.
According to vLLM, DeepInfer was originally built on vLLM, and it reached these results by integrating DeepSeek's open-source kernels and extensively optimizing prefill and decode. The post includes a performance chart; the figures are vLLM's own and have not been independently checked. The post had about 307 likes on X by October 24.
Sources
Get news like this as a push.
AI Tracker alerts you when something changes for the tools you use.