 AI Tracker
MiniMax lists community quantizations for running M3.1 Flash locally
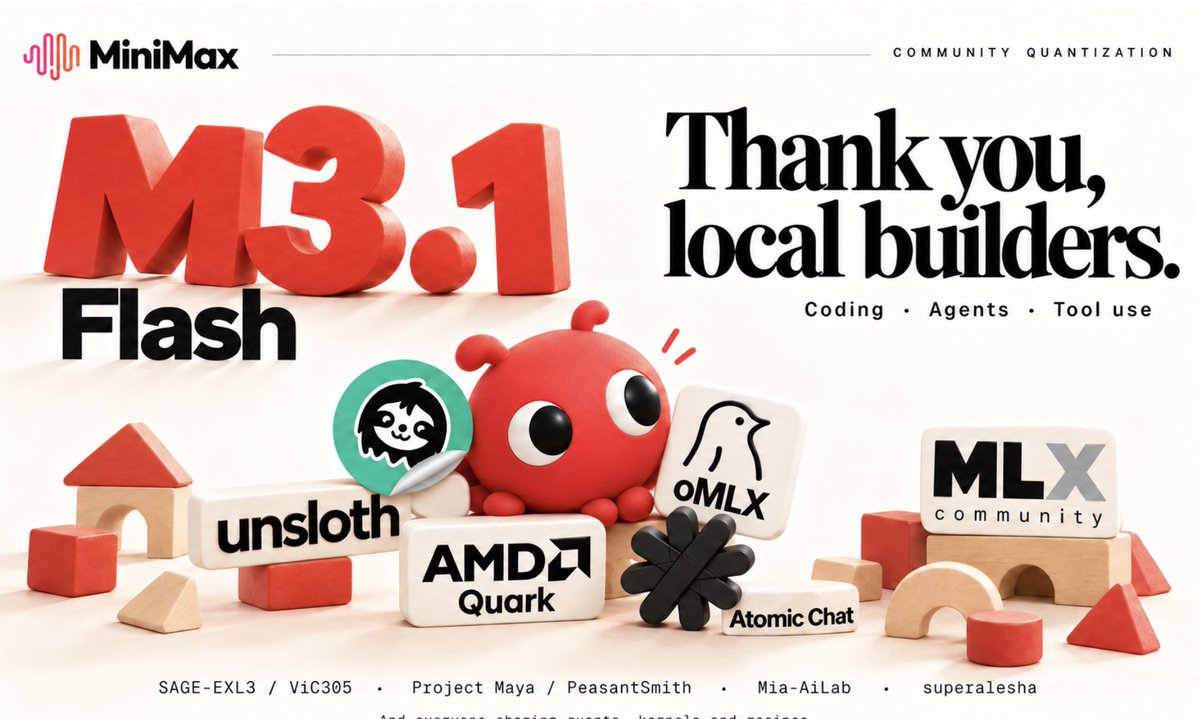
MiniMax posted a roundup of community-made quantized versions of its 428B-parameter open-weight M3.1 Flash, aimed at people running it on their own hardware. MiniMax says lower-bit weights cut the memory needed to load the model and the weight data moved during decoding, and that making this useful takes careful calibration, efficient low-bit kernels and placing experts across GPU and system RAM.
The builders it credits:
- Unsloth: 2-bit Dynamic GGUF weights at 143.9 GB, with calibration and fidelity testing across coding, tool use and other workloads.
- ViC305: SAGE-EXL3 quants, token-level fidelity measurements and a single-DGX-Spark recipe.
- PeasantSmith: Project Maya quants and expert offloading for local coding and tool use.
- MiaAI_lab: EXL3-EAQ quantization work.
- jundotkim and mlx-community: oQ quants, with DSpark-powered decoding through oMLX on Apple Silicon.
- AMD (AIatAMD): Quark MXFP4 adapted for AMD Instinct.
- atomic_chat_hq: GGUFs for local desktop workflows.
- superalesha: custom inference combining quantized weights, expert caching and system RAM on four RTX 3090s.
The fidelity claims come from the quantizers themselves, not from MiniMax or an independent test. The post had about 400 likes on X by November 1.
Sources
- MiniMax M3.1 Flash, on more of your hardware.X · 36 comments
Get news like this as a push.
AI Tracker alerts you when something changes for the tools you use.