 AI Tracker
Artificial Analysis and Arena rank Kimi K3.1 Pro 4th on their indexes and #8 in Code Arena WebDev
Two independent evaluators published results for Moonshot's Kimi K3.1 Pro within an hour of its launch. Both put its price at $2 per million input tokens and $10 per million output tokens; Artificial Analysis lists cached input at $0.20, 33% below Kimi K3.
Artificial Analysis says the model scores 55 on its Intelligence Index, 11 points above Kimi K3 (44) and 4th overall, behind Claude Opus 5.5 (58), Claude Sonnet 5.5 (56) and Muse Wonder Full (56). Its other figures:
- It is 3rd on GDPval-AA with 1,846 Elo, up 312 from Kimi K3.
- It has the highest Terminal-Bench 4.0 score of any model it has tested, 67% (Kimi K3: 13%; Claude Sonnet 5.5: 64%).
- AutomationBench-AA rises from 58% to 73%. Gains on Humanity's Last Exam (47% to 52%), CritPt (23% to 25%) and SciCode (59% to 61%) are smaller.
- Its hallucination rate on AA-Omniscience falls from 53% to 44%.
- Cost per task is about $1.98, roughly level with Kimi K3, because it uses 14% more output tokens.
- Once the weights are published, Artificial Analysis says it would be the highest-scoring open-weights model, narrowing the gap to proprietary models from 12 points to 3.
Arena says the model is #8 in Code Arena: WebDev with 1692 points, up 9 places and 37 points from Kimi K3, matching Claude Opus 5 (Max) at what it calls 70% lower cost. Its median cost per task is $1.23, 29% less than Kimi K3. Arena also reports #7 in Brand & Marketing and #9 in Simulations, and says that with open weights it would be the top open model in WebDev, ahead of DeepSeek V4.1 Flash.
Artificial Analysis Cyber Index (posted later in the day): Kimi K3.1 Pro scores 64%, up 23 points from Kimi K3 (41%). Artificial Analysis says that makes it the top openly available model and second overall, behind only OpenAI's trusted-access GPT-6 Sol (Daybreak Blue, max) at 69%, and ahead of DeepSeek V4.1 Flash 1017 (57%). It reports the highest CyberGym-E2E-AA score of any model it has tested (95%), 37% on DeepsecBench-AA and 61% on CWE-Bench-AA (DeepSeek V4.1 Flash 1017 leads there with 69%), and no safety refusals. Cost per task is $2.81, 15% above Kimi K3, because it uses about twice the input tokens.
Extended NYT Connections (Lech Mazur's independent benchmark, posted later in the day): Kimi K3.1 Pro (high) scores 93.4, slightly below Kimi K3 at 93.6, while using fewer reasoning tokens. Mazur also tested GPT-6 Astra (max) and GPT-6.1 Sol (max); Gemini 4 Argon (high) remains first.
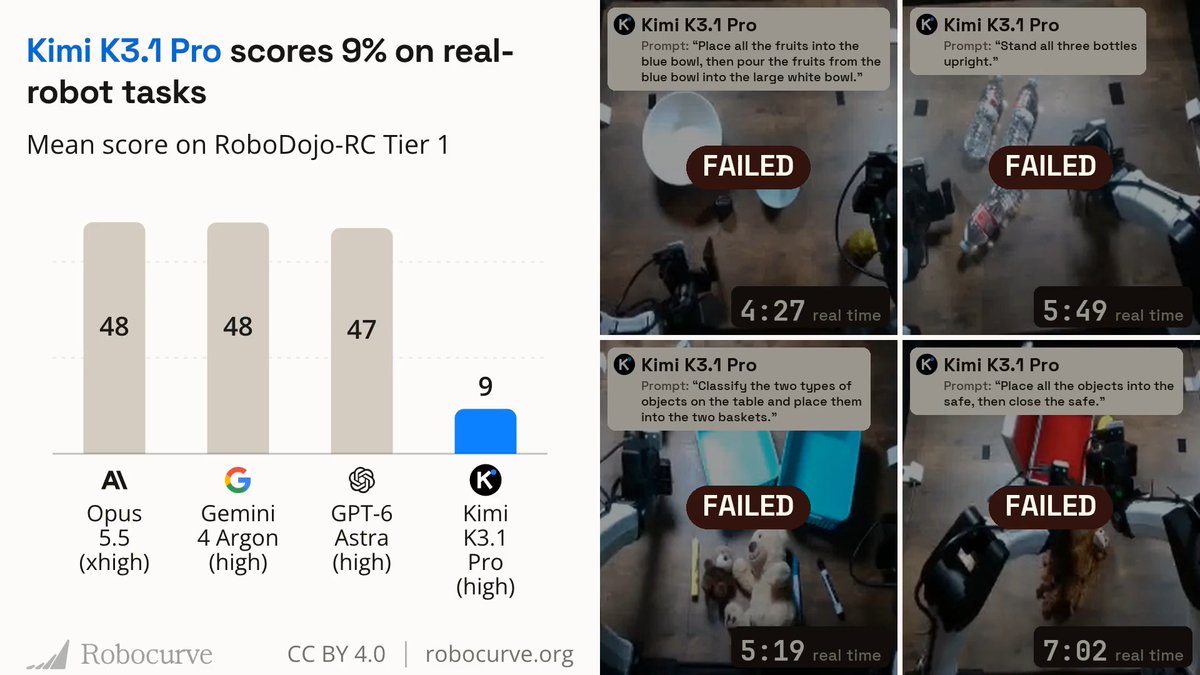
Robocurve real-robot tasks (posted that evening, Pacific time): Robocurve, a physical-AI benchmarking organization, says Kimi K3.1 Pro scores 9% on its real-robot tasks, behind Claude Opus 5.5, Gemini 4 Argon and GPT-6 Astra.
Agent Arena (posted October 24 by Arena): Kimi K3.1 Pro (Max) enters the Agent Arena at #11, with a net improvement of 7.6% across more than 4,000 real-world agentic sessions from Arena's users. Arena says that would make it the top open model in the Agent Arena, ahead of DeepSeek V4.1 Flash.
VulnPR-100 (posted October 24 by a user running BugBunny's benchmark): given 100 pull requests with known vulnerabilities and one hour per PR, Kimi K3.1 Pro found 47 for $124.69, 10 more than Kimi K3 at $20.54 less. A relayed post adds that DeepSeek V4.1 Flash 1017 found 54 for $7.53.
Mazebench (posted October 24 by its author): Kimi K3.1 Pro scores 2%, which the post calls the first nontrivial score for an open-weights model; DeepSeek V4.1 Flash scores 1%.
Design Creativity Bench (posted October 24 by its maintainer): Kimi K3.1 Pro's overall creativity score rises from 40.4 to 45.8 against Kimi K3. Its appropriateness score rises from 96.8% to 98.5%, which the benchmark's post says is ahead of every other open-weight model it has evaluated and level with Claude Fable 5.1. It generates designs nearly twice as fast as Kimi K3, and median cost per design falls 18%, from $0.570 to $0.466.
DesignArena Website leaderboard (posted October 24 by DesignArena): Kimi K3.1 Pro is projected to rank #1 among open-weights models and tied for #3 overall, behind only Muse Wonder (max) and Muse Spark 1.3 (xhigh) and level with Muse Spark 1.3 Max. DesignArena says it leads Kimi K3 by 15 Elo points on the open-weights leaderboard.
LLM Creative Story-Writing Benchmark (posted October 24 by Lech Mazur): Kimi K3.1 Pro (high) scores 2.72, up from 2.35 for Kimi K3. On 50 matched prompts it records 35 wins, 8 ties and 7 losses against Kimi K3. Mazur says the main gain is stronger plotting, with required elements shaping characters' decisions and their consequences more consistently, and that it uses 34% fewer reasoning tokens.
Sources
- Big news: @Kimi_Moonshot is back in the top-4 labs in the Code Arena: WebDev with the release of Kimi K3.1 Pro!X · 3 comments
- Kimi K3.1 Pro launches at 4th on the Artificial Analysis Intelligence Index scoring 55, making large gains in agentic performance; it will…X · 13 comments
- Kimi K3.1 Pro (high) scores slightly lower than Kimi K3 on the Extended NYT Connections Benchmark: 93.6 → 93.4. But it uses fewer…X · 1 comments
- Kimi K3.1 Pro scores 9% on real-robot tasks, behind Opus 5.5, Gemini 4 Argon and GPT-6 Astra.…X · 15 comments
- Kimi K3.1 Pro is now live on Design Creativity Bench!X · 2 comments
- Kimi K3.1 Pro (Max) by @Kimi_Moonshot just landed in the Agent Arena at #11 with +7.6% net improvement across +4K real-world agentic…X · 1 comments
- We gave Moonshot’s new Kimi K3.1 Pro 100 pull requests with known vulnerabilities and one hour per PR to find them in the @BugBunny_ai…X · 10 comments
- Mazebench vs Kimi K3.1 vs DeepSeek v4.1X · 9 comments
- Kimi K3.1 Pro (high) improves over Kimi K3 on the LLM Creative Story-Writing Benchmark: 2.35 → 2.72.X · 3 comments
- BREAKING: Kimi K3.1 Pro by @Kimi_Moonshot is projected to rank #1 among open-weights models on DesignArena's Website leaderboard, and is…X · 19 comments
Discussions
- Kimi K3.1 Pro vs. Claude Opus 5.5 ⚔️X · 4 comments
- Kimi K3.1 scores 55 on Artificial Analysis, placed on the Pareto lineHacker News · 20 comments
- Kimi K3.1 scores 55 on Artificial Analysis, placed on the Pareto lineHacker News · 38 comments
- So I tested Kimi K3.1 Pro on real work. 2 repos. 105 replanted bugs. Find and fix what you can. The results:X · 11 comments
- Kimi K3.1 Pro is the new #1 openly-available model for agentic cyber defense, behind only trusted-access model GPT-6 Sol (Daybreak Blue)…X · 11 comments
- Kimi K3.1 Pro 这个Terminal-Bench 4.0——average cost per task 的图相当鸡贼。。。X · 3 comments
- Kimi K3.1 Pro 猫榜AGENT测试出分了。。。。。。X · 3 comments
- Kimi K3.1 Pro vs. Opus 5.5 vs. GPT-6 AstraX · 4 comments
- Kimi K3.1 is basically the open-weight version of Opus 5.5 / GPT-6 Astra, but way cheaperX · 79 comments
- Wow.. 😲 Here's definitive results of Kimi-K3.1-Pro's offensive cybersecurity capabilities. These are black-box engagements, run on…X · 10 comments
- Kimi K3.1 Pro vs. DeepSeek V4.1 Flash vs. MiniMax M3.1 Flash ⚔️X · 5 comments
Get news like this as a push.
AI Tracker alerts you when something changes for the tools you use.