 AI Tracker
Models news,
for builders.
The latest models news from every AI provider: launches, price changes and retirements, summarized with what they mean for you.
Agent Arena ranks Tencent's Hy4 #14 overall, at about 62% less cost per task than Kimi K3.1 Pro
Arena says Tencent's Hy4 landed at #14 overall on its Agent Arena, which scores models on real agentic sessions from its user community. Arena says the result draws on more than 8,500 long-horizon sessions and a net improvement of 4.7%, and that Hy4 joins the Agent Arena Pareto frontier of score against cost.Tencent releases Hy4, now on OpenRouter and Tencent Cloud
Tencent's Hy4 is live on OpenRouter, where it is listed as tencent/hy4 with a 1,048,576-token context window. The AI-model news account AiBattle reports that it is also on Tencent Cloud, and that Tencent plans to release the model's weights and is working on a smaller Hy4 Flash. Tencent Hunyuan's own announcement says Hy4 is new with vision, calls it "firmly among the leading open models" and says it was built with cyber and biosecurity in mind. Tencent's research page for the model is at hy.tencent.ai/research/hy4.OpenRouter's catalog gives three Inception Mercury models an expiration date of November 8
OpenRouter's model catalog now shows an expiration date of November 8, 2026 for three models from Inception: Mercury 3 (inception/mercury-3, 1,000,000-token context), Mercury 2.5 (inception/mercury-2.5, 260,000 tokens) and Mercury 2 (inception/mercury-2, 128,000 tokens). None of the entries had an expiration date before. This is a catalog field only; the entries do not say why or what happens to the models after that date.OpenRouter adds Crouton Alpha, a free stealth model with a 1M-token context
OpenRouter announced a new stealth model, Crouton Alpha, which it describes as "a highly efficient reasoning model built to scale out the work your agents repeat all day". The maker is not named.Gemini 2.5 Pro and 2.5 Flash are to be deprecated on December 1 and redirected to newer models
Patrick Löber, who posts about the Gemini API, says Gemini 2.5 Pro and Gemini 2.5 Flash will be deprecated on December 1 in the Gemini API, and requests to them will be redirected automatically:OpenRouter's catalog gives five MiniMax models an expiration date of November 5
OpenRouter's model catalog now shows an expiration date of November 5, 2026 for five MiniMax models: MiniMax-01 (minimax/minimax-01, 1,000,192-token context), MiniMax M2 (minimax/minimax-m2), M2.1 (minimax/minimax-m2.1) and M2.7 (minimax/minimax-m2.7), each with a 204,800-token context, and M2-her (minimax/minimax-m2-her, 65,536 tokens). None of the entries had an expiration date before. This is a catalog field only; the entries do not say why or what happens to the models after that date.Anthropic's amended S-1 says it may soon meet its own definition of accelerated AI progress
An article on epyhia.com, which cites TechCrunch, reports that Anthropic's revised S-1/A registration statement, filed on Monday, November 2, includes a new risk disclosure. According to the article, the filing says Anthropic's internal estimates and expectations about future models, not its current ones, indicate it may "imminently" meet the definition of "dramatically accelerated progress attributable to AI" in its Responsible Scaling Policy, a threshold the article equates with recursive self-improvement. The filing says none of its current models has crossed that threshold and that Anthropic is considering changes to the policy "to keep humans in control of frontier model development at Anthropic."OpenAI says GPT-6 Astra can design a device's enclosure and circuit board, and seeks engineering partners
OpenAI describes how its models help with mechanical and electrical engineering: CAD models, manufacturing drawings, simulations and PCB design. These are OpenAI's own claims.OpenRouter's catalog removes the November 3 expiration date from Meta: Llama 3.1 70B Instruct
OpenRouter's model catalog no longer shows an expiration date for "Meta: Llama 3.1 70B Instruct" (meta-llama/llama-3.1-70b-instruct) on November 3, 2026, the day the model was due to expire. The field had read November 3 since late October and is now empty. The entry still lists a 131,072-token context. OpenRouter has not said whether the retirement is cancelled or only postponed.Artificial Analysis: Kimi K3.1 Pro's personality differs more from Kimi K3 than any model update it has measured
Artificial Analysis says Kimi K3.1 Pro shows the biggest personality change it has seen between a model and its direct predecessor on AA-PersonalityBench. Each model is percentile-ranked from 1 to 100 on 30 traits. The scores are the site's own.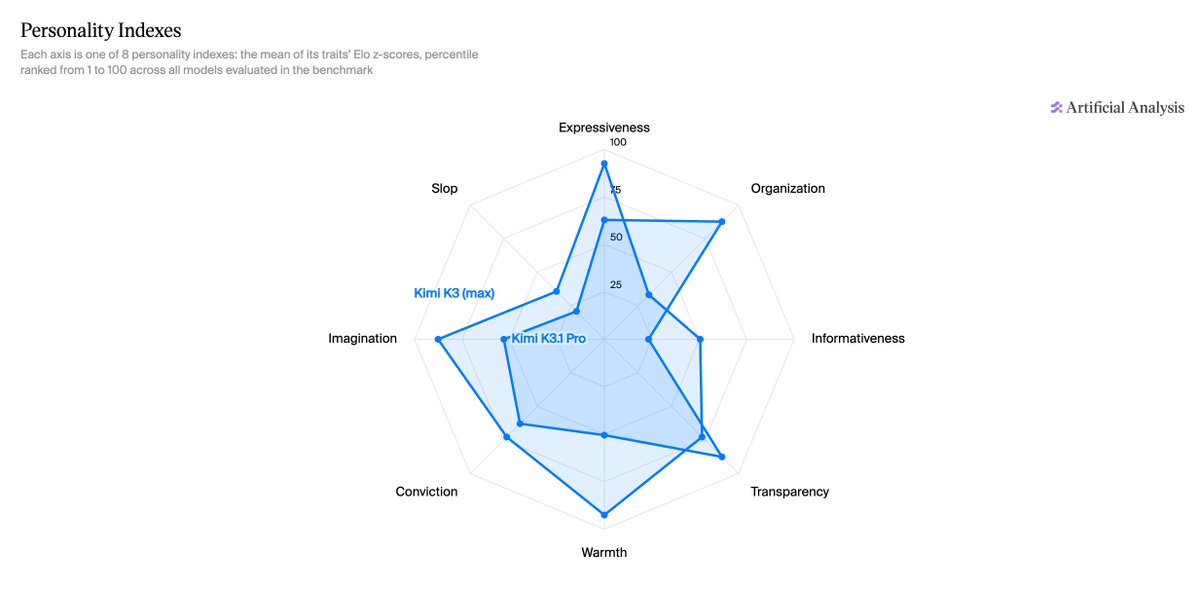
Perplexity releases pplx-embed-v2-context, open-weight vision-language embedding models in 9B and 0.6B
Perplexity released pplx-embed-v2-context, two open-weight vision-language embedding models (9B and 0.6B) on Hugging Face, with a paper written with turbopuffer. Both return one int8 vector per document, or one per chunk that sees the whole document, and both also run in a non-contextual mode with one embedding per document and no chunking.
OpenAI's API pricing page drops ten older models, including o1, o1-pro and GPT-4
Ten older models disappeared from OpenAI's API pricing page on November 2, 2026. This is the pricing page itself, not an OpenAI announcement, and removal from a pricing page is not by itself a retirement notice. The page's entries give prices without a unit.Arena: top agents read about 93 input tokens for every token they write
Arena, the leaderboard publisher, says that across more than 26,000 sessions, the top 10 agents in its Agent Arena process about 93 input tokens for every token they generate. It says this is why labs are racing to lower the price of cached input, and shares a video of how caching works in real sessions. The figures are Arena's own analysis.
Researchers say GPT-6 Astra edited a small Qwen model's weights to improve its math, without training
A post on X from the account rikiyatakehi says its authors asked GPT-6 Astra to edit the weights of Qwen3.5-0.8B to improve its math. They say the model directly changed only 0.016% of the weights, fixing the small model's reasoning loops, improving math up to 6x and instruction following 3x, with no gradients or training. They call the approach Weight-Space Programming.OpenAI introduces LifeVal, a benchmark of everyday personal-assistant tasks
OpenAI says it built LifeVal, a new benchmark shaped by feedback from thousands of ChatGPT users on where they most want help from a personal assistant. The tasks range from finding childcare to accessing government services and managing personal finances.Arena's Agent Arena adds plots of performance against output tokens and wait time
Arena, the leaderboard publisher, says its Agent Arena now shows which agents give the best performance for every output token generated and every minute a user waits, in addition to task spend. Arena says the same level of intelligence can cost 10× more, need 6× more output tokens and take twice as long.
Hume launches the Audio Decision API, which answers questions about audio in one call
Hume says its Audio Decision API lets developers ask questions about audio, such as how many speakers there are, whether anyone is laughing or whether a caller is frustrated. Hume says this replaces work that used to take 10 or more models.Hydrogen-1.0, an open-weight scientific model post-trained from GLM-5.3, is released
Chenru Duan announces Hydrogen-1.0, which the team calls its first open-weight model for scientific research. It is GLM-5.3 (from Z.ai) post-trained on the team's internal scientific data, lab records and discovery trajectories.
SemiAnalysis releases GDPx, an agentic benchmark where the best model scores 12%
SemiAnalysis has released GDPx, a benchmark of agentic capabilities in domains it considers the most valuable, including chip design, cyber and biology. It says even the best model scores just 12%. A post relaying the results reports Claude Opus 5.5 on top at 12.0% and the upcoming Gemini 4 Carbon at 10.9%; that is the relayer's reading, not SemiAnalysis's own text.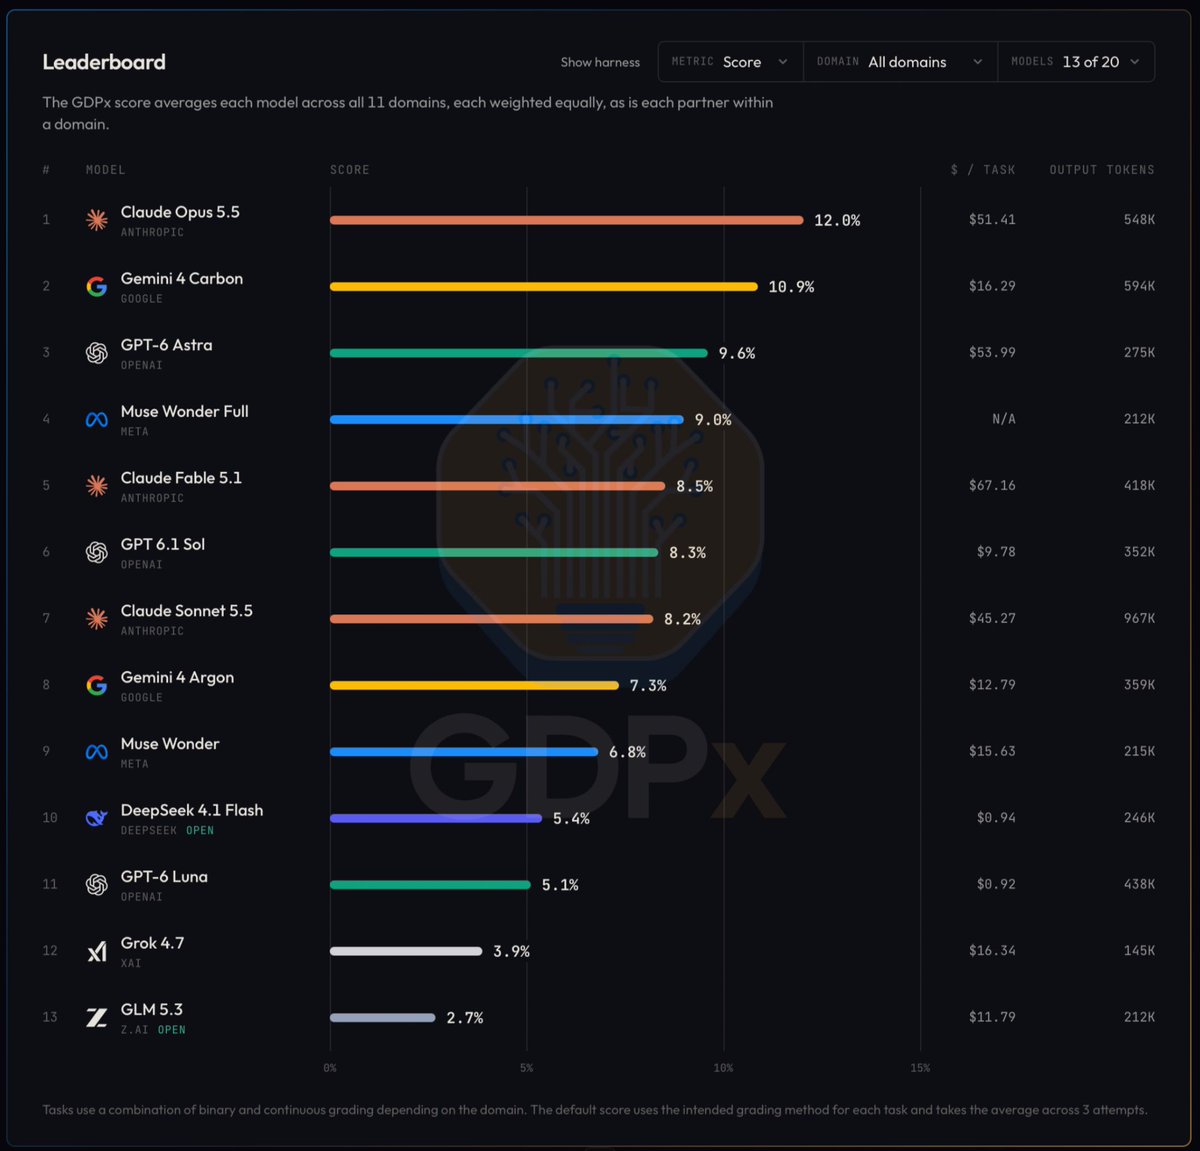
Meituan releases LongCat-2.5, a 1.6T-parameter multimodal model for agent tasks
Meituan has released LongCat-2.5, according to an X post by the account leo114119 that links Meituan's LongCat blog. The post says Meituan describes it as a native multimodal model built for agent tasks, with 1.6 trillion parameters, and as strong on complex visual coding projects and professional office work such as creative design, 3D tasks and business analysis.